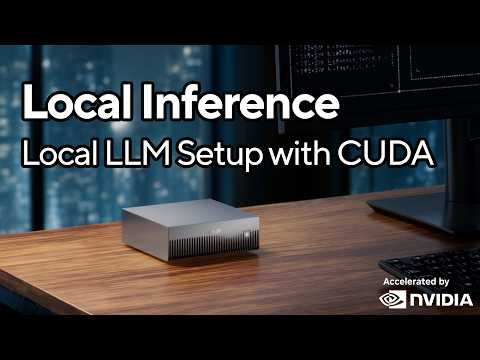
In this demo, we showcase how the ASUS Ascent GX10, powered by the @NVIDIA GB10 Grace Blackwell Superchip, runs large language models locally using llama.cpp, a lightweight C/C++ inference framework optimized for high-performance AI workloads.
By building llama.cpp with CUDA support, tensor operations are accelerated on the GX10 GPU, enabling fast, efficient on-device inference without relying on cloud infrastructure or heavyweight AI frameworks.
The result is a complete local AI inference pipeline, from model loading to GPU-accelerated inference and API serving, all running entirely on the GX10.
Whether you’re building AI applications, experimenting with local LLMs, or deploying private AI solutions, the ASUS Ascent GX10 provides a powerful platform for fast, flexible, and secure AI development.
🔗 Learn more: https://site.tdsynnex.com/nvidia-asus/p/1
#ASUS #NVIDIA #LocalAI #agenticai #CUDA #tensor #LocalLLM
For more information head over to:
► ASUS Website: http://www.asus.com/
► LinkedIn: https://www.linkedin.com/company/asus
► Facebook
ASUS: https://www.facebook.com/asus.n.america
► Instagram
ASUS: http://instagram.com/asususa
► Twitter
ASUS: https://twitter.com/ASUSUSA
► TikTok: https://www.tiktok.com/@asusbusiness