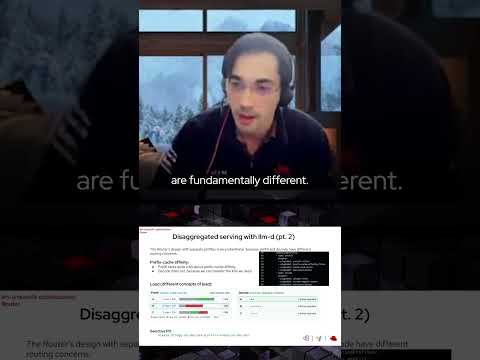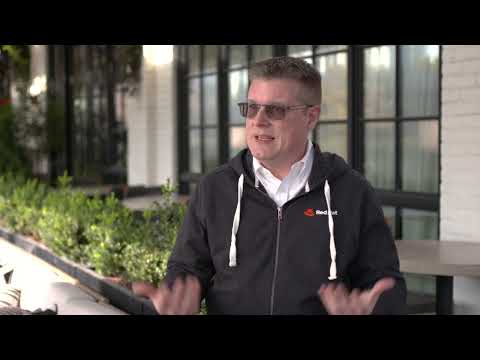

Discover how llm-d improves vLLM inference efficiency by preventing KV cache duplication across multi-GPU deployments. Traditional L7 load balancers use naive round-robin routing, causing up to 50% KV cache duplication and higher latency in multi-turn LLM serving. Greg Pereira, Senior Machine Learning Engineer at Red Hat, explains how llm-d introduces a prefix-based prefill and decode (PD) decider.
Learn how independent routing decisions for prefill and decode optimize prefix cache affinity and token load scoring across GPUs.
00:00 The challenge of scaling Models-as-a-Service
00:22 Why traditional L7 load balancing fails vLLM
00:45 KV cache duplication and latency issues
01:16 Selective PD disaggregation with llm-d
01:56 How the prefix-based PD decider works
02:18 Prefill vs. decode routing concerns
03:02 Calculating token load score for prefill
From vLLM Office Hours #55: Mooncake + vLLM/llm-d Deep Dive. Full session: https://youtu.be/RFyeBEy1AP8
Join us live every other Thursday: https://red.ht/office-hours
#vLLM #llm-d #KVCache #AIInference #RedHat #MLOps